
MLOps Services
Deploy, monitor, evaluate and retrain AI in production, so a model that worked at launch keeps working next quarter.
OZRIT provides MLOps and AIOps services for teams running machine learning and language-model applications. We build the pipelines, monitoring, evaluation and cost controls that turn a one-off model into a dependable service, whether it was built by us or by you.
Tell us what you need
A consultant replies within one business day. No sales deck.
- 17+years building softwareFounded in Hyderabad in 2009
- 500+in-house engineersFull-time, not freelancers
- ISO/IEC 27001:2022certifiedFor information security
- 98%client retentionLong-term partnerships
MLOps and AIOps, explained
Models do not fail loudly. They drift, quietly, until the numbers stop making sense.
MLOps is the discipline of running machine learning in production: versioning models and data, deploying them through repeatable pipelines, monitoring quality and drift, and retraining when performance drops. LLMOps applies the same ideas to language-model applications, where prompts, retrieval and model versions all change behaviour. AIOps is the related practice of using AI to monitor and manage IT operations.
Without these practices, AI projects tend to follow the same pattern: a strong launch, then slow decline as data changes, costs creep up and nobody can say which version is running or why an answer changed. OZRIT builds the operational layer so problems are caught by monitoring, not by users.
We can take over a model you already run, put the pipeline and monitoring around it, and set up evaluation that is run on every change. For new builds, we design operations into the project from the first sprint, so launch day is not the point where the engineering stops.
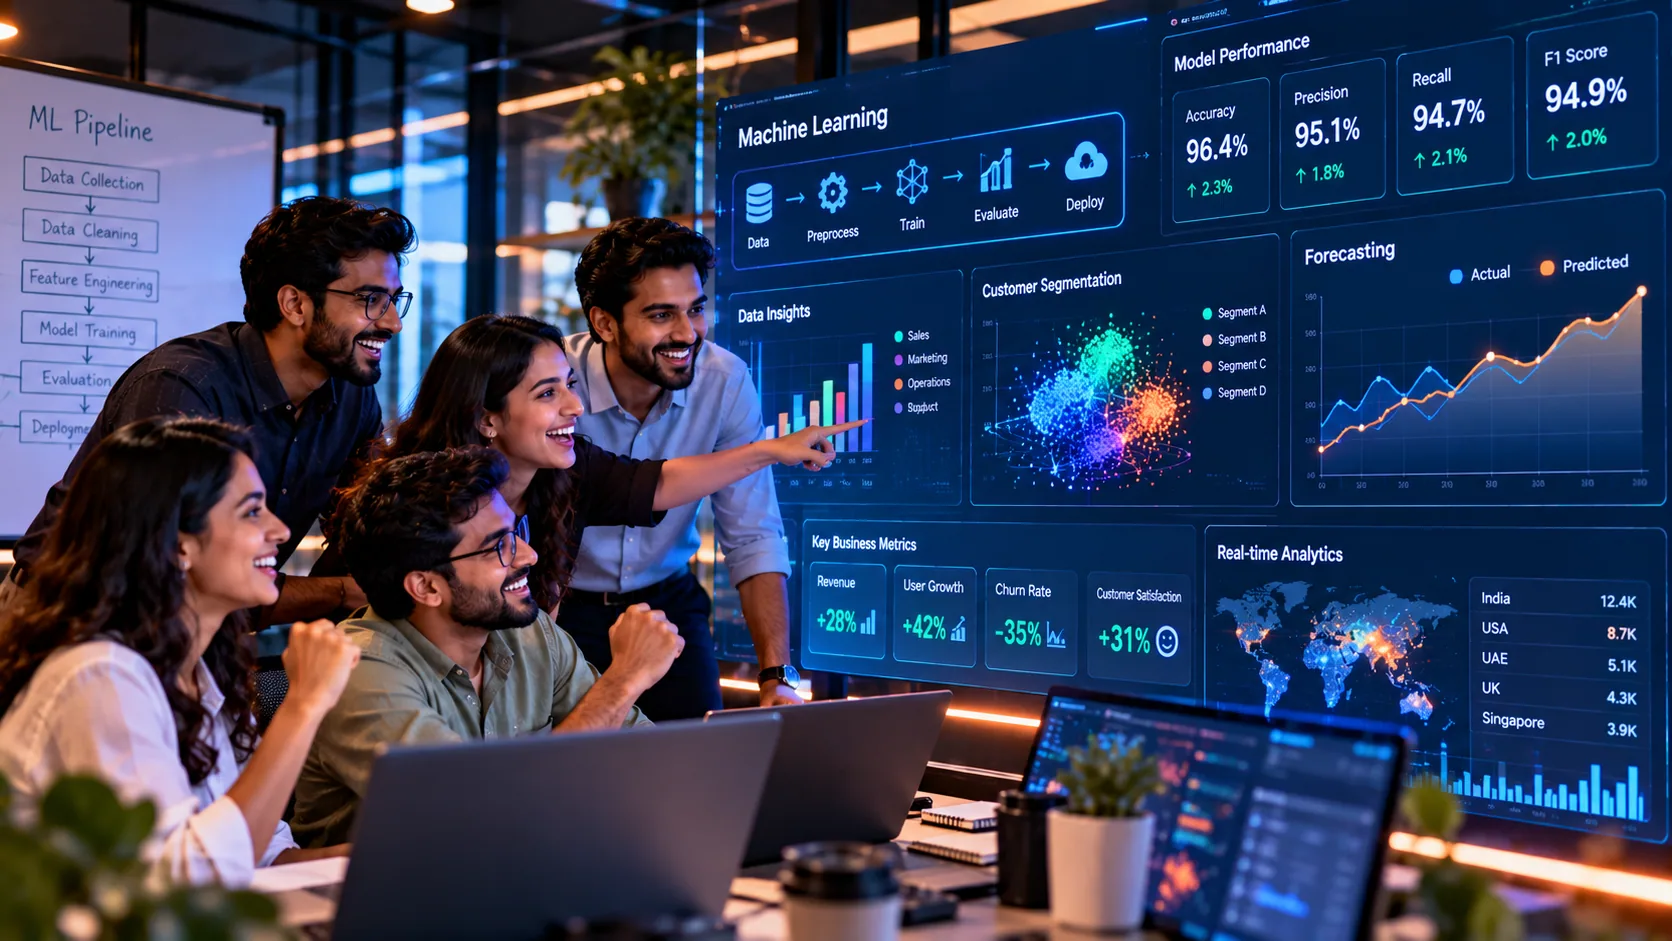
- Deployment pipelines
- Model and data versioning
- Quality and drift monitoring
- Automated evaluation
- Retraining pipelines
- Cost, latency and uptime tracking
MLOps and AIOps services we offer
The operational layer that keeps AI accurate, affordable and auditable.
Deployment pipelines
Repeatable CI/CD for models and prompts, with testing gates, staging and safe rollback.
Model and data versioning
Track which model, prompt, data and code produced each result, so changes are traceable.
Quality and drift monitoring
Watch accuracy, input patterns and output behaviour over time, with alerts when they shift.
Automated evaluation
Test sets run on every change, including for language models, so regressions are caught before release.
Retraining pipelines
Scheduled or triggered retraining on fresh data, with checks before a new model replaces the old.
Cost, latency and uptime tracking
Dashboards and alerts for spend per feature, response times and availability.
LLMOps and prompt management
Versioned prompts, retrieval monitoring, guardrail checks and model-routing for language-model apps.
Governance, audit and access
Model registries, approval workflows, access control and audit logs for regulated use.
How we set up MLOps
Six steps from a model that runs to a service you can rely on.
Assess and operate
Pipeline and monitoring in roughly 4 to 8 weeks
- 1
Assess how the AI runs today
We review how models are deployed, monitored, updated and paid for, and where the risks are.
- 2
Define quality and cost targets
We agree the metrics that show the AI is healthy: accuracy, drift, latency, cost and uptime.
- 3
Build the pipelines
We set up versioning, deployment, evaluation and retraining pipelines that run without manual steps.
- 4
Add monitoring and alerts
We add dashboards and alerts so a drop in quality or a jump in cost reaches the right person.
- 5
Test failure and rollback
We rehearse bad releases and outages so recovery is quick and safe.
- 6
Operate and improve
We run monthly reviews, retrain when needed and tune cost, or hand the operation to your team.
MLOps use cases
Where operational discipline matters most.
Forecasting and prediction models
Demand, risk and churn models that need retraining as behaviour and markets change.
LLM and RAG applications
Assistants whose answers shift with prompts, content and model versions.
Fraud and risk scoring
Models where drift or bias must be spotted and explained quickly.
Recommendation engines
Systems that must keep up with changing catalogues and customer behaviour.
Computer vision in production
Models affected by lighting, product and camera changes on the line.
AI in regulated sectors
Healthcare, banking and insurance models that need audit trails and approval workflows.
MLOps and AIOps for your industry
The same build applies across sectors, but the data, rules and risks differ. These are the industries where we are asked for it most.
Fintech app development
Fraud signals, credit scoring, document checks and support assistants for lenders, payments and banks.
Healthcare app development
Record summaries, triage support, scheduling and personalised plans for providers and health-tech teams.
Retail and eCommerce app development
Product search, recommendations, demand forecasting and support assistants for stores and marketplaces.
Logistics app development
Route planning, ETA prediction, proof-of-delivery checks and exception alerts for fleets and supply chains.
Education app development
Tutoring assistants, content generation, assessment help and engagement analytics for learning platforms.
Real estate app development
Lead qualification, property search, valuation support and document handling for developers and brokers.
The technology behind our MLOps
We build on open tools and the platforms you already use, so you are not tied to a single vendor.
Pipelines and registry
Build, version, deploy
- MLflow
- Kubeflow
- Airflow
- DVC
- GitHub Actions
- Docker
Monitoring
Quality, drift and cost
- Prometheus
- Grafana
- Evidently
- OpenTelemetry
- LangSmith
- CloudWatch
Serving
Models in production
- FastAPI
- KServe
- BentoML
- TorchServe
- Kubernetes
- Redis
Cloud and deployment
In your cloud account or ours
- AWS Bedrock and SageMaker
- Azure OpenAI and ML
- Google Vertex AI
- Docker
- Kubernetes
What decides the cost of MLOps
MLOps is priced by how many models you run and how much automation you want around them.
Number of models and apps
Each model or application needs its own pipeline, tests and monitoring.
Current maturity
Moving from manual deployment is more work than improving an existing pipeline.
Evaluation depth
Rich test sets and human review add effort, especially for language models.
Retraining frequency
Frequent retraining needs more automation and compute.
Compliance requirements
Audit trails, approvals and access control raise the design effort.
Run versus handover
Operating the service for you is a monthly plan, while handover is a one-off project.
Security and privacy in MLOps and AIOps
A security or compliance team will ask where the data goes, who can see it and how quality is checked. These are the safeguards we build into every project.
Where your data lives
Models can run in your own cloud account or on private endpoints, with provider settings that stop your data being used for training. You choose the region.
Access control
Assistants respect the permissions of the person asking. Someone who cannot open a document cannot get its content through a chat window either.
Testing before launch
We build an evaluation set from your real cases and measure accuracy, safety and cost before and after every change, not just once at launch.
Certification and ownership
OZRIT is ISO/IEC 27001:2022 certified for information security. You own the code, prompts, models you commission and your data.
All eight AI safeguardsCertifications and AI frameworks we work to
MLOps services: frequently asked questions
Straight answers on cost, timelines, data, security and ownership.
What are MLOps services?
MLOps services set up and run the processes around machine learning in production: deployment pipelines, versioning, monitoring, evaluation, retraining and governance. They keep models accurate, affordable and auditable over time.
What is the difference between MLOps, LLMOps and AIOps?
MLOps covers running machine learning models in production. LLMOps applies similar ideas to language-model applications, including prompts and retrieval. AIOps means using AI to monitor and manage IT operations. We cover MLOps and LLMOps for your AI, and can advise on AIOps tooling.
How much do MLOps services cost?
It depends on how many models you run, how mature your current process is and how much automation you want. A discovery sprint from $1,000 assesses your set-up and ends with a scoped quote.
How long does it take to set up MLOps?
A pipeline with monitoring for a first model usually takes 4 to 8 weeks. Wider estates, strict compliance or many models take longer, and we agree the plan before you commit.
Can you take over a model someone else built?
Yes. We review the model, data and code, put it into a repeatable pipeline, add monitoring and evaluation, and document it so that your team or ours can run it.
How do you detect model drift?
We monitor input data and output behaviour against a baseline, track accuracy where ground truth arrives, and alert when distributions or quality move beyond agreed limits. Then we investigate and retrain if needed.
How do you test language-model applications?
We build evaluation sets from real questions and expected behaviours, run them on every change to prompts, retrieval or models, and score accuracy, safety and tone. Regressions are caught before release.
Can you reduce our AI running costs?
Often. We track cost per feature, use caching and batching, route simple tasks to cheaper models and right-size infrastructure, while keeping quality above the targets you set.
Do you work with our cloud and tools?
Yes. We work with AWS, Azure and Google Cloud, with open tools such as MLflow, Kubeflow and Airflow, and with the platforms you already pay for, so you avoid unnecessary lock-in.
Can you run the operations for us?
Yes. We can operate the service on a monthly plan, with reviews, retraining and cost tuning, or build it and hand it over to your own team with documentation and training.
Get your AI production-ready
Tell us what you run today and what worries you about it. We will say what monitoring and automation would help most, and what it would take.
What happens next
- 1An AI consultant reads your note and may reply with a few questions.
- 2We hold a call to understand the problem, your data and the systems involved.
- 3If AI fits, we propose a discovery sprint or a scoped pilot with clear success measures.